High-availability cache with automatic failover
Keep cache and sessions online when a node dies — automatic promotion instead of a single point of failure.
Problem
Applications that store cache and sessions in memory go dark the moment that one node fails. A single instance is a single point of failure. Manual failover is slow, easy to get wrong, and usually happens at the worst time.
The platform needs the cache layer to stay available: detect the dead node, promote a replica, and reconnect clients without an operator in the loop.
System Design
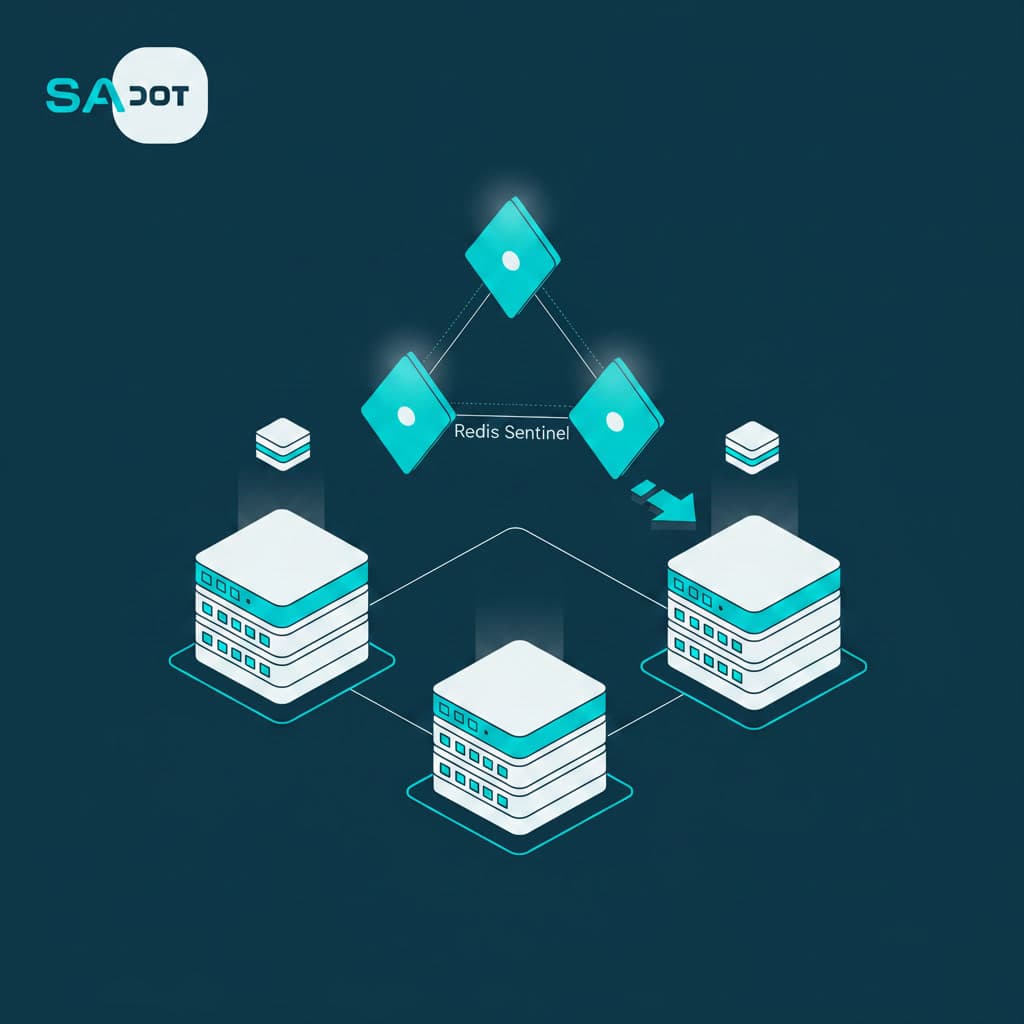
This project is a three-node in-memory cluster plus three monitors on a shared overlay network. One node starts as primary; the others replicate. The monitors watch the primary and, if it disappears, elect a replica automatically.
Designed for cache and session workloads — data stays in memory, not on disk. Set a password, then deploy. Other services reach the cluster over the overlay network.
Architecture Decisions
- Quorum-based monitoring so a majority must agree before failover
- Password in cluster secrets, not in git
- Startup logic that finds the current primary and repairs replication after failover
- Overlay network so other stacks can connect without hard-coded hosts
- Scripts for deploy, status, and teardown
- Layouts that spread services across multiple cluster nodes
Tradeoffs
- No disk persistence — fast and simple, but data is gone if the whole cluster dies
- Clients should discover the current primary, not pin a fixed address
- Config changes require a redeploy
- Real high availability needs at least three nodes
Production Behavior
Set the password and deploy. Monitors watch the cluster and switch the primary when needed. Replicas reconnect on their own — no manual steps.
Check health after deploy. Built for cache layers where recovering in seconds matters more than writing every key to disk.